Adds a cookbook recipe + runnable showcase that gives the Built-in Agent
OAuth-backed Arcade tools (Gmail, Google News) and renders Arcade's one-time
authorization step as a generative-UI "Connect" card in the chat.

- docs: showcase/shell-docs/src/content/docs/cookbook/arcade.mdx (+ meta.json, index card)
- app: examples/showcases/arcade-tools (Next.js App Router, single-route runtime)

Co-authored-by: Cursor <cursoragent@cursor.com>
- Add control-plane-run.test.ts (17 tests) covering buildLocalServicesJson,
  expectedKeys, dedupeScopes, and runViaControlPlane error surfacing
- Export SlugScope, buildLocalServicesJson, expectedKeys, dedupeScopes
  for unit-test coverage (factored inline dedup loop into dedupeScopes
  helper at the same time)
- runViaControlPlane: surface scopeLabel (demo-aware) in the 0-enqueue
  error instead of the bare-slug join, with an empty-targets guard so
  the error never renders with a double-space gap
- runViaControlPlane: treat tick.enqueueFailures > 0 as fatal — partial
  enqueue used to silently proceed and either mask missing cells or
  hang the poll loop to timeout
- Eliminate a stray literal NUL byte in the source by switching the
  dedup key separator to a \x00 escape
- lifecycle.up(): name the compose call (infra-up vs target rebuild)
  in the health-fail error so an operator can tell which call left a
  service unhealthy

(cherry picked from commit 9f35c64adfdf7f5ff2bf0a5ae57ed03818cea607)
CR Finding 1 (BLOCKER): d5-tool-rendering-default-catchall.ts used the
broken page.evaluate(fn, arg) second-arg form to pass the leak-phrase
needle into the browser-side closure. A11 proved empirically that the
arg arrives as undefined inside the closure, making 'if (needle)' guard
the entire leak-detection cascade as dead code — customLeakPhrasePresent
stayed false forever, rendering validateDefaultCatchall's leak branch
dead code as well. Mirrors the A11 fix on the sibling custom-catchall
probe by inlining the needle as a JS string literal inside the closure;
no page.evaluate(fn, arg) dependency at all. Both probes now share the
same inline-needle pattern and keep the canonical literal in lock-step
with their exported phrase constant.

CR Finding 2 (MAJOR): the A11 inline-needle fix on the sibling
custom-catchall probe had no regression test — fake Page.evaluate in
makePageReturning never executes the probe closure, so reverting the
fix would not be caught. Added regression tests that capture the
probe's function source via toString() and assert (a) the canonical
phrase appears as a literal inside the page.evaluate(...) closure and
(b) the closure takes no parameter / the evaluate call has no
second arg. Added the same coverage to default-catchall to protect
the new A25a fix.

CR Finding 3 (MAJOR): A7's requireContentPhrase=true branch in
validateCustomCatchall / assertCustomCatchall had zero coverage —
tests omitted the third arg and exercised only the default false
branch. Added coverage for the true branch (pass on phrase present,
fail on phrase absent, fail on phrase undefined, default-branch
preserved) plus assertCustomCatchall plumbing through the options
form. Also added coverage for default-catchall's customLeakPhrasePresent
branch in validateDefaultCatchall for symmetry.

Local proof:
- RED (fix reverted via git stash): 2 inline-needle regression tests
  fail on d5-tool-rendering-default-catchall.test.ts
- GREEN (fix restored): 34/34 tests pass across both files

Out of scope (NOT touched this commit): showcase/harness/src/cli/
control-plane-run.ts and lifecycle.ts (A25b's scope).

(cherry picked from commit c409e3a8d99e16ad0bb05ee3c2e2051e5792049f)
Re-tier the showcase docs tree to be an agent entry point: README.md
opens with a 'when X, see Y' fanout table that routes to the right
procedural doc; each procedural doc gets a one-line tagline answering
'what does this answer'.

Consolidation:
- DELETE showcase/RUNBOOK.md — operational content merged into DEBUGGING.md
  (Integration Patterns, Docker Compose Environment, Production Debugging,
  Anti-Patterns, Aimock Fixture Deployment, Dev Iteration Speed). The
  --isolate mechanics + CLI rules were already duplicated in DEBUGGING.md.
- DELETE showcase/QA-COVERAGE.md — per-demo coverage matrix + starter hero
  matrix + probe depth + infra locations + gaps folded into TESTING.md as
  the 'Per-Demo Coverage Matrix' section.

Taglines added (no behavioral change to content): TESTING.md, DEBUGGING.md,
GOTCHAS.md, INTEGRATION-CHECKLIST.md, STYLING-GUIDE.md, FRONTEND-STRATEGY.md,
RAILWAY.md, bin/README.md, aimock/README.md, aimock/RAILWAY.md,
harness/README.md, harness/docs/rotation-drill.md.

Cross-link fixups: FRONTEND-STRATEGY.md (was QA-COVERAGE.md →
TESTING.md#per-demo-coverage-matrix), TESTING.md (removed dangling RUNBOOK
companion reference), README.md (rewritten as fanout entry + retained
from-scratch setup + dashboard SOPs below the fanout).

PARITY_NOTES.md × 12 left alone (per-slug context, not redundant).

(cherry picked from commit 75c9d9755c9118c8abc1fa52deda2012b768cab1)
(cherry picked from commit b64189bae0fe2c9e3a5e3ca440013deb4121f23b)
New content:
- TESTING.md: add 10-step cell red→green SOP + bin/showcase test invocation
  table (control-plane vs --direct, per-demo scoping matrix); retain
  existing CI gating matrix below.
- GOTCHAS.md: add operational gotchas — aimock caches fixtures at container
  startup (warm-slot reuse needs docker restart) + --isolate slot collisions
  with foreign Docker projects.
- README.md: cross-link to TESTING.md SOP from CLI section; flesh out
  --isolate / --direct in test options table; update use cases.
- RUNBOOK.md: update Verifying a Slug's D6 State to use auto-named --isolate;
  note A21+A21b per-slug rebuild scoping; rewrite Fixture Matching to teach
  picking the backend-id-invariant discriminator (turnIndex post-A12/A13/A20);
  modernize Debugging Sequence to --isolate flow.
- DEBUGGING.md: lead with TESTING.md SOP cross-link; update Phase 1 to
  --isolate canonical; soften turnIndex-only log-line description; note
  aimock startup caching in Phase 5; switch Strategy 5 gold-standard check
  to --isolate.

Pruned/updated stale claims (post-A11/A12/A13/A18/A20/A21/A21b):
- RUNBOOK.md "Do not use turnIndex in new fixtures" — turnIndex is now
  the canonical backend-id-invariant alternative when toolCallId is fragile
  (Anthropic / TanStack Responses API ID rewrites). Replaced with discriminator
  selection guidance.
- RUNBOOK.md anti-pattern "NEVER use turnIndex" — replaced with NEVER
  anchor on toolCallId strict equality against ID-rewriting backends, and
  NEVER use --direct for value-tests.
- RUNBOOK.md bin/showcase test <slug> --d5 (no --isolate) as canonical SOP
  — replaced with --isolate canonical, no manual name required.
- README.md --d5 option description claiming "subagents/tool-rendering/agentic-chat"
  fixed slate — replaced with "defaults to agentic-chat representative; :demo
  qualifier honored post-A18".
- DEBUGGING.md Phase 1 "showcase up aimock <slug> && showcase test <slug> --d5"
  as primary — kept as legacy alternative; --isolate is now lead.
- DEBUGGING.md Phase 5 "fixtures baked into Docker image" — clarified that
  aimock additionally caches fixtures in memory at startup (volume-mounted
  isolated stack still requires docker restart for warm-slot edits).
- DEBUGGING.md Strategy 5 "showcase test langgraph-python --d5" — replaced
  with :demo + --isolate so the gold-standard check exercises the same cell.

(cherry picked from commit 0e548455043396972f7fb5b96f8c0ea8abdf1d98)
(cherry picked from commit 592c02d392350d02cc5e17544e663a6605b8da65)
Mirrors A19b's BIA fix pattern for the Anthropic-family csdkts integration.

Root cause: csdkts uses Anthropic SDK which generates its own toolCallIds (toolu_*) rather than echoing aimock's prescribed call_d6_cc_*. The fixture's toolCallId-gated narration entries never matched on turn-2, causing fall-through to less-specific entries (or 503/no-match).

Fix: replace toolCallId discriminator with turnIndex (count of role:assistant messages). turnIndex is backend-id-invariant — it works regardless of how the backend rewrites tool_call_id values. Same shape as A19b BIA fix.

- Tokyo narration: toolCallId → turnIndex: 1
- AAPL narration: toolCallId → turnIndex: 3
- AAPL emit: added turnIndex: 2
- Tokyo emit: turnIndex: 0

response.content + canonical phrase ("rendered through the custom wildcard catchall") and response.toolCalls UNTOUCHED.

Verified locally on cr5495/fix-a20-csdkts-green at HEAD d178e6730 (post-A21b):
- /tmp/cr/a20v6-green-csdkts.log: 1 passed, INNER_EXIT=0
- iso2 slot, full infra healthy (aimock+pocketbase+dashboard+csdkts)

(cherry picked from commit e66e0eb0ce72c970348183eeb4f4b57c3f5b1d29)
A21 (a9114a831) regression: positional slug after 'up' restricted which services start (only target+depends_on came up; infra profile services never started). With concurrent sibling stack on same host ports, health checks crossed to foreign pocketbase → cell results misrouted → 0.0s red. Fix: split into 2 compose calls — (1) compose infra up -d, then (2) compose --profile slug up -d --build slug. Preserves A21's target-only rebuild + restores full infra stack.

(cherry picked from commit d71ff46edb4a7b0a89f89d8126fd5fe3d5c7d24e)
Root cause
----------
Both the shell `cmd_up` (showcase/bin/showcase line 98) and the harness
auto-start path (showcase/harness/src/cli/lifecycle.ts up() line 268) emit
`docker compose up -d --build` with NO positional service filter after `up`.
Under `docker compose` semantics, an unfiltered `--build` rebuilds EVERY
service in every active profile — for `--isolate` runs that means the
target slug PLUS aimock + pocketbase + dashboard + harness-pool-worker
all rebuild on every isolated test invocation.

Concurrent `--isolate` runs (one per `SHOWCASE_ISO_SLOT=<N>`) contend on
the shared BuildKit instance, serializing what should be parallel work.
This is the BuildKit-contention stall that has been blocking csdkts (A20)
when it runs alongside other concurrent isolated cells: a small slug
rebuild waits on every other slot's full-stack rebuild.

Fix
---
Scope `--build` to the targeted slug(s) by passing them as positional
service args AFTER `up`. Compose then rebuilds ONLY those services and
falls through to cached images for infra services. First-time bootstrap
still works because `--build` only FORCES a rebuild of services with an
existing image — missing images are built automatically by compose.

Two call sites:
 - showcase/bin/showcase  (user-facing `showcase up <slug>...`)
 - showcase/harness/src/cli/lifecycle.ts (npx tsx test path, the one
   actually triggered under `--isolate`)

When no slugs are provided (infra-only bring-up), the blanket `--build`
is preserved so first-time infra bootstrap rebuilds whatever is missing.

`--rebuild` regression: the `--rebuild` flag goes through `rebuild()`,
not `up()`, and that path is unchanged — it still force-rebuilds and
force-recreates every targeted slug as before.

Red→Green proof
---------------
3 new vitest cases in showcase/harness/src/cli/lifecycle.test.ts assert
the compose argv shape:
 - up(["langgraph-python"]): slug positional after `up` (was: missing)
 - up([]):                  no slug positional (infra-only blanket)
 - up(["a","b"]):            both slugs as positionals after `up`

Pre-fix:  2 failed | 4 passed (6)
Post-fix: 0 failed | 6 passed (6)

The compose-argv assertion is the deterministic proof of behavior
change. Wall-clock timing improvement on concurrent --isolate runs
follows mechanically from the compose semantics: with the fix, slot
N's BuildKit work no longer blocks slot M's because they only rebuild
their respective slug images, not the shared infra stack.

(cherry picked from commit 8a47dbb0d2a2fe72e21c09a824485e1bb5afc463)
Replace per-leg toolCallId pin with turnIndex (assistant-count) +
userMessage on the two narration fixtures, and add explicit turnIndex
to the AAPL-emit fixture, so first-match-wins partitions the four
request shapes BIA produces against the OpenAI Responses API.

Root cause:
- BIA uses @tanstack/ai-openai openaiText('gpt-4o') which calls
  /v1/responses. aimock converts each /v1/responses request to a
  chat-completions-shaped completionReq via responsesInputToMessages()
  and matches with the same router. The matcher's toolCallId check is
  strict equality against the last message's tool_call_id.
- BIA's TanStack runtime auto-generates tool_call_id at request time
  (e.g. 'fc-fCgLtvquOtRpCJTM'), so the fixture-side literal
  'call_d6_cc_weather_001' / 'call_d6_cc_stock_001' never matched.
  Result: 503 STRICT no-fixture-match on the narration turns, BIA
  agent looped on AAPL emit indefinitely.

Fix shape:
- Tokyo narration: toolCallId -> turnIndex: 1
- AAPL narration: toolCallId -> turnIndex: 3 (was off-by-one until I
  accounted for the Tokyo-narration assistant message itself adding
  to the assistant-count tally seen at AAPL emit time)
- AAPL emit: add turnIndex: 2 so first-match-wins partitions emit vs
  narration on the second prompt's two turns

Verification (worktree wt-5495-a19-bia-record, slot iso6):
- RED: bin/showcase test built-in-agent:tool-rendering-custom-catchall
  --d5 --isolate -> state=red, 0 passed/1 failed, INNER_EXIT=1
  (aimock journal: 3x 503 'No fixture matched' on turn-2 narration
  request; AAPL emit fixture matched repeatedly = infinite loop)
- GREEN: same command, post-fix and aimock-restart so the container
  reloads the fixture -> state=green, 1 passed, INNER_EXIT=0; aimock
  journal: 4 requests, all 200, clean progression
  Tokyo-emit (asstCount=0) -> Tokyo-narrate (asstCount=1) ->
  AAPL-emit (asstCount=2) -> AAPL-narrate (asstCount=3)
- LGP regression: bin/showcase test
  langgraph-python:tool-rendering-custom-catchall --d5 --isolate ->
  state=green, 1 passed, INNER_EXIT=0 (uses its own fixture under
  aimock/d6/langgraph-python/ — untouched by this change)

Constraints honored: response.content and response.toolCalls
preserved verbatim; canonical narration phrases unchanged; only the
match keys (and their explanatory _comment fields) were modified;
other integrations' fixtures and the harness probe were not touched.

(cherry picked from commit 60d027a1376ba72309b5b3fcf94cc26c64757307)
Before A18, `bin/showcase test <slug>:<demo> --d5/--d6` routed through the
control-plane runner but `runViaControlPlane()` collapsed every TestTarget
to its bare slug:

  const slugs = [...new Set(targets.map((t) => t.slug))];

`target.demo` was silently dropped, and:

  - `buildLocalServicesJson` hardcoded `demos: ["agentic-chat"]` for d5 and
    the full demo set for d6 — regardless of what the operator typed.
  - `expectedKeys` always emitted the level's DEFAULT-scope key
    (`d5:<slug>/agentic-chat` for d5, `d6:<slug>` aggregate for d6).

The net effect on d5: typing `built-in-agent:tool-rendering-custom-catchall
--d5` enqueued the agentic-chat representative, ran agentic-chat in the
worker fleet, and wrote the side row `d5:built-in-agent/agentic-chat` —
green in ~0.0s — while the dashboard reported PASS for a cell the run
never exercised. Validation was dishonest by construction; the CLI claim
of per-demo coverage was substituted with the default representative.

Fix (additive):
  - Introduce a per-call SlugScope = { slug, demo? } and thread it through
    `buildLocalServicesJson` + `expectedKeys` + `runViaControlPlane`.
  - When `target.demo` is set:
      * `LOCAL_SERVICES_JSON` synthesizes `demos: [<demo>]` (the worker's
        d6 driver reads `input.demos` → `demosToFeatureTypes` → the closed
        featureType set, so the matrix narrows to exactly that demo's
        featureType(s)).
      * `expectedKeys` translates the demo ID into its featureType(s) via
        the same `REGISTRY_TO_D5` mapping the driver uses, and waits on
        `<level>:<slug>/<featureType>` — NOT the default-scope key. An
        unmappable demo throws (would otherwise hang to timeout).
  - When `target.demo` is absent: zero behavioral change. d5 still
    enqueues the agentic-chat representative and waits on
    `d5-single-pill-e2e:<slug>` + `d5:<slug>/agentic-chat`; d6 still
    enqueues the full demo set and waits on the `d6:<slug>` aggregate.
  - CLI banner now prints the per-scope label (`<slug>:<demo>` qualifier
    when present), mirroring the legacy direct path's labeling.

Repro (built-in-agent:tool-rendering-custom-catchall, --d5 --isolate):

  BEFORE
    Waiting for worker fleet to produce cells:
        d5-single-pill-e2e:built-in-agent, d5:built-in-agent/agentic-chat
    ✓ 2 passed (0.0s)        ← agentic-chat representative ran;
                               catchall never touched. False-positive.

  AFTER
    Waiting for worker fleet to produce cells:
        d5:built-in-agent/tool-rendering-custom-catchall
    ✗ 1 failed: state=red    ← catchall actually ran. Cell is RED at
                               this HEAD (BIA narration→DOM is a
                               separate task A12). Validation is now
                               HONEST.

Regression: bare-slug d5 default UNCHANGED:

    built-in-agent --d5  →
        d5-single-pill-e2e:built-in-agent, d5:built-in-agent/agentic-chat
    ✓ 2 passed (0.0s)

Files:
  showcase/harness/src/cli/control-plane-run.ts  (+96 -17)
    - import demosToFeatureTypes
    - SlugScope interface
    - buildLocalServicesJson: per-slug demo override
    - expectedKeys: per-demo featureType-derived keys; refuse-loud
      on unmappable demo
    - runViaControlPlane: (slug, demo) dedup; scope-aware banner/log
(cherry picked from commit 82ae79279415b7eaf91759df4d8bc1625816a8c3)
Pre-existing crewai backend defect: tool-rendering-custom-catchall agentId was routed to the shared LatestAiDevelopment ChatWithCrewFlow at /, with no get_weather/get_stock_price handlers. tool_result never returns, second LLM call never fires, toolCallId-gated narration fixture entries unreachable, A7 requireContentPhrase=true probe fails.

Fix: add get_stock_price_impl in src/agents/tool_rendering.py mirroring LGP-python tool shape; re-route 'tool-rendering-custom-catchall' agentId in src/app/api/copilotkit/route.ts to createAgent('/tool-rendering').

Local verification on cr5495/fix-a14-crewai-green:
- /tmp/cr/a14-green-crewai.log: 1 passed (6.8s), INNER_EXIT=0
- /tmp/cr/a14-green-lgp.log (LGP regression): 1 passed (9.0s), INNER_EXIT=0

(cherry picked from commit 208d90018a3fc41c263fd4514b104c78815f8303)
- Rename the opt-out section to "Disable default tool rendering" and lead
  with the wildcard (all tools), then a "For specific tools" subsection,
  so it reads least-specific to most-specific.
- Drop the useFrontendTool handler/schema boilerplate from the opt-out
  example; both cases now use a schema-free useRenderTool call.
- Document the new render-only (no-schema) useRenderTool overload on the
  useRenderTool reference page.
Root cause (A11 investigation, PR #5495): the probe passed the canonical
phrase into the browser-side `page.evaluate` closure via the second-arg
form (`evaluate((expectedPhrase?: string) => …, phrase)`). Empirically
the arg arrives as `undefined` inside the closure — verified via
in-closure return diagnostics showing `needleLen === 0` while
`bubble.textContent` and `body.textContent` BOTH contained the canonical
phrase at the SAME poll moment. With `needle === """, the
`if (needle)` guard skipped the entire cascade, leaving
`customContentPhrasePresent` false forever and failing every
integration's `tool-rendering-custom-catchall` cell even when the
narration was reaching the DOM correctly (LGP gold).

Fix: inline the canonical phrase as a JS literal inside the closure —
no `page.evaluate(fn, arg)` second-arg dependency. Keep the existing
per-tier scoped cascade and `body.textContent` fallback semantics
unchanged. The shared constant `CUSTOM_CATCHALL_CONTENT_PHRASE` and
the inlined literal MUST stay in lock-step (existing
`exports the testid contract for cross-test reuse` unit test verifies
the constant; manual sync required on edit of the literal).

RED-GREEN proof:
  RED (pre-fix, /tmp/cr/a11-red-lgp.log INNER_EXIT=1):
    LGP `d5-single-pill-e2e:langgraph-python red`
    settled text turn 2 = 'AAPL is trading at $338.37, down 2.96% —
    rendered through the custom wildcard catchall renderer.' (phrase
    IS in bubble.textContent) but
    snap.customContentPhrasePresent: false  ← THE BUG

  GREEN (post-fix, /tmp/cr/a11-final-lgp.log INNER_EXIT=0):
    LGP `d5-single-pill-e2e:langgraph-python green (8.9s) → 1 passed`

BIA remains red (separate fixture-routing concern — BIA's narration is
not reaching the DOM at all per `settled text` = pure tool-card text,
`assistantMsgCount: 2`, no canonical-phrase bubble; outside this
fix's scope per the worktree's modify-harness-only constraint).

(cherry picked from commit a980be48c514a2ab4972395e80e70e5b19247131)
Other dimension drivers under showcase/harness/src/probes/drivers/ follow
the dN-<purpose>.ts naming pattern (d4-chat-roundtrip.ts, d6-all-pills.ts).
D2 and D3 didn't — bring them in line.

  drivers/liveness.ts        -> drivers/d2-liveness.ts
  drivers/liveness.test.ts   -> drivers/d2-liveness.test.ts
  drivers/e2e-readiness.ts   -> drivers/d3-readiness.ts
  drivers/e2e-readiness.test.ts -> drivers/d3-readiness.test.ts

The d3 driver loses the redundant 'e2e' prefix — the dimension is D3
and the corresponding dashboard badge is 'UI', so the file's job is best
described as 'is the demo frontend ready?'.

Imports updated in:
  - showcase/harness/src/orchestrator.ts
  - showcase/harness/src/orchestrator.test.ts
  - showcase/harness/src/cli/runner.ts
  - showcase/harness/src/probes/drivers/d2-liveness.test.ts (self-ref)
  - showcase/harness/src/probes/drivers/d3-readiness.test.ts (self-ref)

Doc-comment references to the old file paths updated in:
  - showcase/harness/src/cli/targets.ts
  - showcase/harness/src/probes/liveness.ts (the helper, not the driver)
  - showcase/harness/src/probes/loader/probe-invoker.ts
  - showcase/harness/src/probes/discovery/railway-services.ts
  - showcase/harness/src/probes/drivers/starter-smoke.ts
  - showcase/harness/src/probes/drivers/starter-smoke.test.ts
  - showcase/harness/src/types/dimensions.test.ts
  - showcase/harness/config/probes/e2e-demos.yml
  - showcase/harness/README.md (driver table)

Function/symbol exports unchanged (livenessDriver, e2eReadinessDriver,
createE2eDemosDriver, etc.) — file rename only. The parent helper module
showcase/harness/src/probes/liveness.ts is also untouched: it's a
separate, non-driver helper that exports deriveHealthUrl, livenessProbe,
and LIVENESS_SLACK_SAFE_FIELDS. Not renamed: drivers/e2e-parity.ts,
drivers/aimock-wiring.ts, drivers/pin-drift.ts, drivers/image-drift.ts
(non-dimensional probes).
The internal counter vars pctBeAgent and totalBeAgent were introduced in
PR #5498 when the display label happened to be "BE (Agent)". The label
has since changed (#5505 made it "API (HTTP)"). Coupling internal variable
identifiers to display labels is fragile — labels move; the underlying
Status enum string "wired" is a persisted contract that does not.

Revert the var identifiers to mirror the enum:

  pctBeAgent   -> pctWired   (coverage-bar.tsx)
  totalBeAgent -> totalWired (cells-view.tsx, parity-view.tsx)

Display labels ("API (HTTP)", etc.) are unchanged — this is internal
identifiers only.
Parent commit 9491b8934 (fix(showcase): disjoint catchall userMessages + content-asserting probes) changed the d5-tool-rendering-custom-catchall probe userMessages to 'Forecast Tokyo through the wildcard renderer' / 'Quote AAPL through the wildcard renderer' but did not add matching entries to LGP-gold's fixture. Result: aimock no-match -> agent_run_error_event -> SSE-missing -> probe RED on LGP with zero bubbles mounted.

This commit adds 4 entries (2 emit + 2 toolCallId-gated narration) following the canonical pattern used by the other 17 integrations. After this commit, LGP bubbles mount and narrations settle with the canonical phrase in bubble.textContent, matching BIA's end-state.

NOTE: A separate fleet-wide probe-layer bug (validateCustomCatchall's customContentPhrasePresent page-wide DOM scan returns false even when phrase is in bubble.textContent) keeps the probe RED in this session. That's a separate concern, to be fixed in a follow-on commit. This commit is a strict improvement: pre-fix LGP got zero bubbles + agent_run_error_event; post-fix LGP renders both bubbles and both narrations settle with the phrase.
(cherry picked from commit 62e04976c3b292a27e1b1cc0bf2bb6fda47db786)
Avoid the provider renderToolCalls literal in the opt-out example,
which required a dummy args schema to typecheck. Point at the
documented useRenderTool wildcard overload (no schema needed) and
link to its reference page instead.
PR #5498 renamed the L1 row "Wired" → "BE (Agent)" for the D2 agent-liveness
dimension (transport/Railway up). PR #5503 renamed the per-cell D4 badge
"RT" → "BE", whose long form was already "BE (Round Trip)". The result was a
same-label-different-concept collision: "BE (Agent)" referred to D2 in some
places while the D4 per-cell badge used "BE (Round Trip)", and the per-cell
D2 badge separately used "API (Agent)" — three names for two concepts.

Normalize the long-form labels so each user-facing layer has exactly one name:

  D2 (transport / Railway up, HTTP-reachable) = "API (HTTP)"
  D4 (agent chat round-trip, end-to-end)      = "BE (Agent)"

That cleanly distinguishes by layer: HTTP transport vs Agent message handling.

Sites touched (visible labels + matching legend prose / test assertions only):
  - stats-bar.tsx, adaptive-stats-bar.tsx — wired count label
  - filter-chips.tsx                       — chip label (id "wired" preserved)
  - packages-section.tsx + .test.tsx       — UWCT legend mnemonic B → A
  - level-strip.tsx + .test.tsx            — agent-dimension badge label (and
                                             derived first letter B → A)
  - cell-drilldown.tsx + .test.tsx +
    cell-drilldown.lazy-signal.test.tsx    — D4 label and D2 label, plus
                                             testid-derivation drift
  - adaptive-legend.tsx                    — D2 / D4 prose

Stable contracts preserved (NOT changed):
  - keyFor("agent" | "d2" | "d4", …) and the "agent" LiveDimension value
  - Filter-chip id "wired"
  - Variable names (`wired`, etc.) — internal; pure label rename is in scope
  - Status enum values "wired" | "stub" | "unshipped" | "unsupported"
  - Driver names, probe registry keys, harness API contracts

Verified: typecheck clean, 1089 pass / 1 skip / 0 fail, build clean.
The per-cell health badge previously labelled "CV" (for "Conversation") is
renamed to "1P" — Single Pill. The new label tells operators what the badge
covers in scope terms (one pill out of N), which is the actual contrast the
D5/D6 ladder draws: D5 driver is `d5-single-pill.ts` (one canonical scripted
conversation), D6 driver is `d6-all-pills.ts` (the full suite). "CV" was
opaque — operators had to remember what "Conversation" meant and how it
differed from D6's full run. "1P vs D6 all-pills" is self-describing.

Mirrors PR #5503's RT → BE pass: only the badge LABEL changes; every stable
contract is preserved.

Stable contracts preserved:
  - Dimension level identifier  `model.d5` / `cell.d5` / `level={model.d5}`
  - Drilldown dimension key     `keyFor("d5", ...)` / `key: "d5"`
  - Probe registry key          `d5:<slug>/<featureId>`
  - PocketBase row keys         unchanged
  - LiveDimension union / Status enum strings  unchanged
  - Driver file names           `d5-single-pill.ts`, `d6-all-pills.ts`
  - `e2e-deep` producer name    unchanged (separate from CV → 1P label)

Updates:
  - Source: badge label in `unified-cell.tsx`, `cell-pieces.tsx`, drilldown
    label in `cell-drilldown.tsx` ("CV (Conversation)" → "1P (Single Pill)"),
    legend text in `adaptive-legend.tsx`, comment refs in `composed-cell.tsx`,
    `cell-model.ts`, `page-stats.ts`, `depth-utils.ts`, `live-status.ts`.
  - Tests: testid strings (`mock-badge-CV` → `mock-badge-1P`), label-text
    assertions, type unions, and comment refs in the affected component +
    drilldown + integration + lib tests.

Verification: typecheck clean, `npm test` = 1089 pass / 1 skip / 0 fail
(same shape as #5503), `npm run build` clean, no remaining `\bCV\b` in
`showcase/shell-dashboard/src/`.
## Summary

Built-in Agent docs now render at bare root URLs, such as `/quickstart`,
instead of under `/built-in-agent`. Legacy `/built-in-agent/*` and
`/integrations/built-in-agent/*` paths continue to redirect to canonical
root or backend URLs.

## Why

The Built-in Agent is the default docs surface, so public docs URLs
should not expose it as a sub-slug. Existing links still need to keep
working, and root-page navigation must stay stable regardless of a
visitor's stored framework selection.

## How

- Root docs resolve Built-in Agent authored pages first while preserving
reserved routes like `/ag-ui` and framework-prefixed docs.
- Redirect rules in `next.config.ts` and `seo-redirects.ts` point
retired Built-in Agent and unselected paths directly at canonical
destinations, with regression coverage that prevents redirect
destinations from targeting `/built-in-agent`.
- The sidebar/framework provider treats bare URLs as the default
Built-in Agent surface instead of letting a stored framework value
rewrite root-page chrome.
- MDX link and search-result href rewriting strip retired Built-in Agent
prefixes on root-rendered pages while preserving explicit
cross-framework links.
- Stale docs links, sitemap, `llms.txt`, markdown exports, and OG
resolution now align with the root-served Built-in Agent surface.
- Showcase generated-data tests now serialize shared fixture restoration
to avoid concurrent drift in CI.

## Verification

- GitHub checks are green on `f655013dd2576a46dc17b5901eb4dc501cb21028`.
- `npm --prefix showcase/shell-docs run test --
src/lib/__tests__/search-hrefs.test.ts
src/lib/__tests__/docs-link-rewrite.test.ts
src/lib/__tests__/seo-redirects.test.ts
src/lib/__tests__/next-config-redirects.test.ts
src/components/__tests__/docs-landing-next.test.tsx
'src/app/[framework]/[[...slug]]/__tests__/framework-root-shell-layout.test.ts'`
- `npm --prefix showcase/shell-docs run test -- --exclude
src/app/__tests__/public-assets.test.ts`
- `npm --prefix showcase/shell-docs run typecheck`
- `npm --prefix showcase/shell-docs run lint`
- `npm --prefix showcase/shell-docs run build`
- `npm --prefix showcase/scripts run test`
- `pnpm exec nx run @copilotkit/bot-slack:build --skip-nx-cache
--verbose`
Sync the v2 useRenderToolCall reference page with the current hook
implementation and document how to opt out of rendering.

- Correct render-prop shape to include toolCallId (added in the hook
  but missing from docs)
- Describe agentId-scoped renderer lookup priority
- Note arguments are parsed with partialJSONParse (streaming), not a
  strict JSON.parse with empty-object fallback
- Fix toolCall prop description (toolCall.function.name/.arguments)
- Rewrite the Status Resolution table to match the real logic
  (toolMessage presence + provider executing set)
- Add an "Opting Out of Rendering" section covering single-tool,
  wildcard, and conditional null renderers
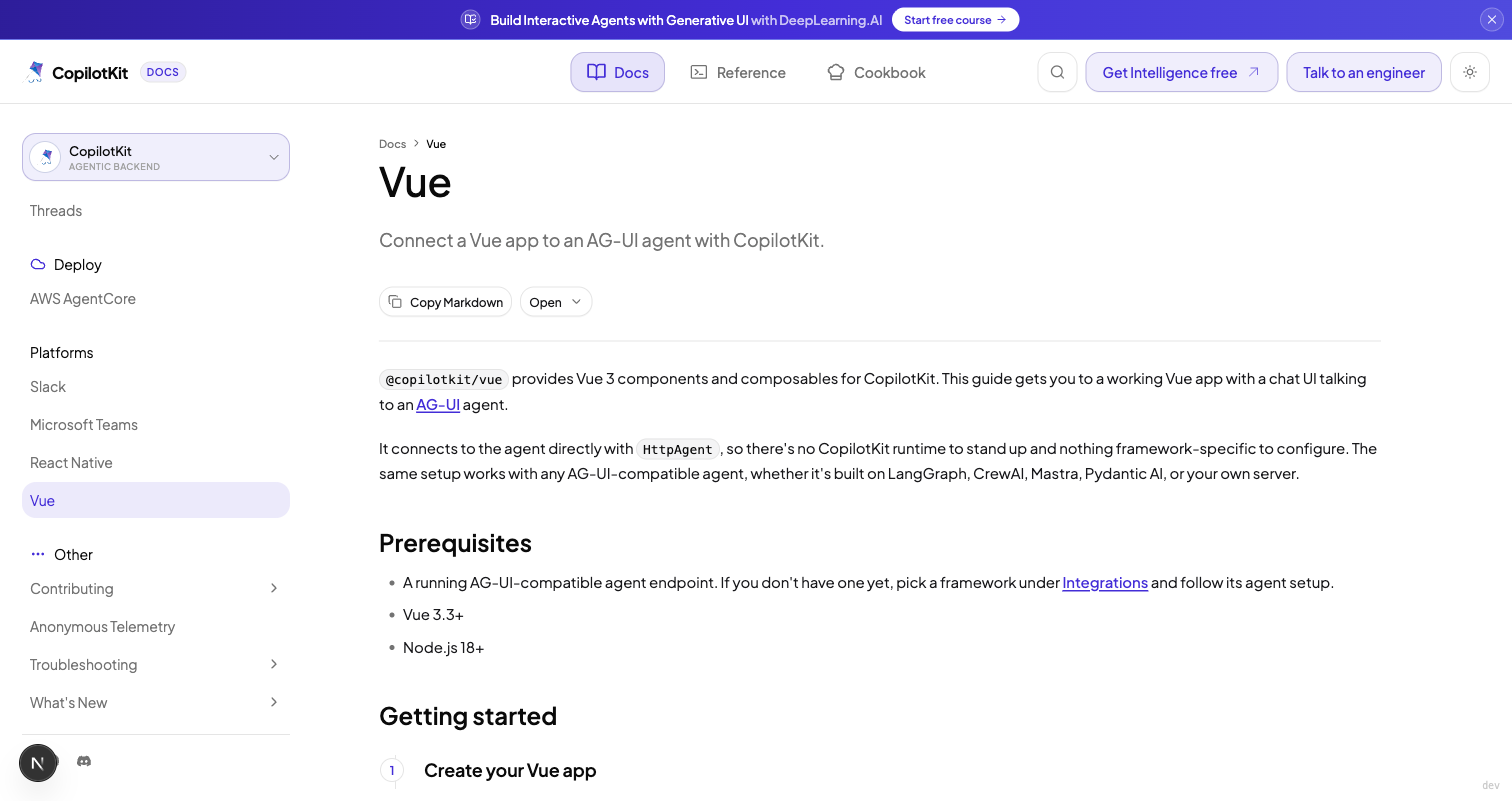
## Vue quick start guide
Adds a minimal getting-started guide for `@copilotkit/vue` under
**Platforms**, matching the existing React Native guide. It connects a
Vue app directly to an AG-UI agent with `HttpAgent`, so there is no
runtime to stand up and nothing framework-specific to configure. The
same setup works with any AG-UI agent, and agent-side setup links out to
Integrations.
### New page
### Changes
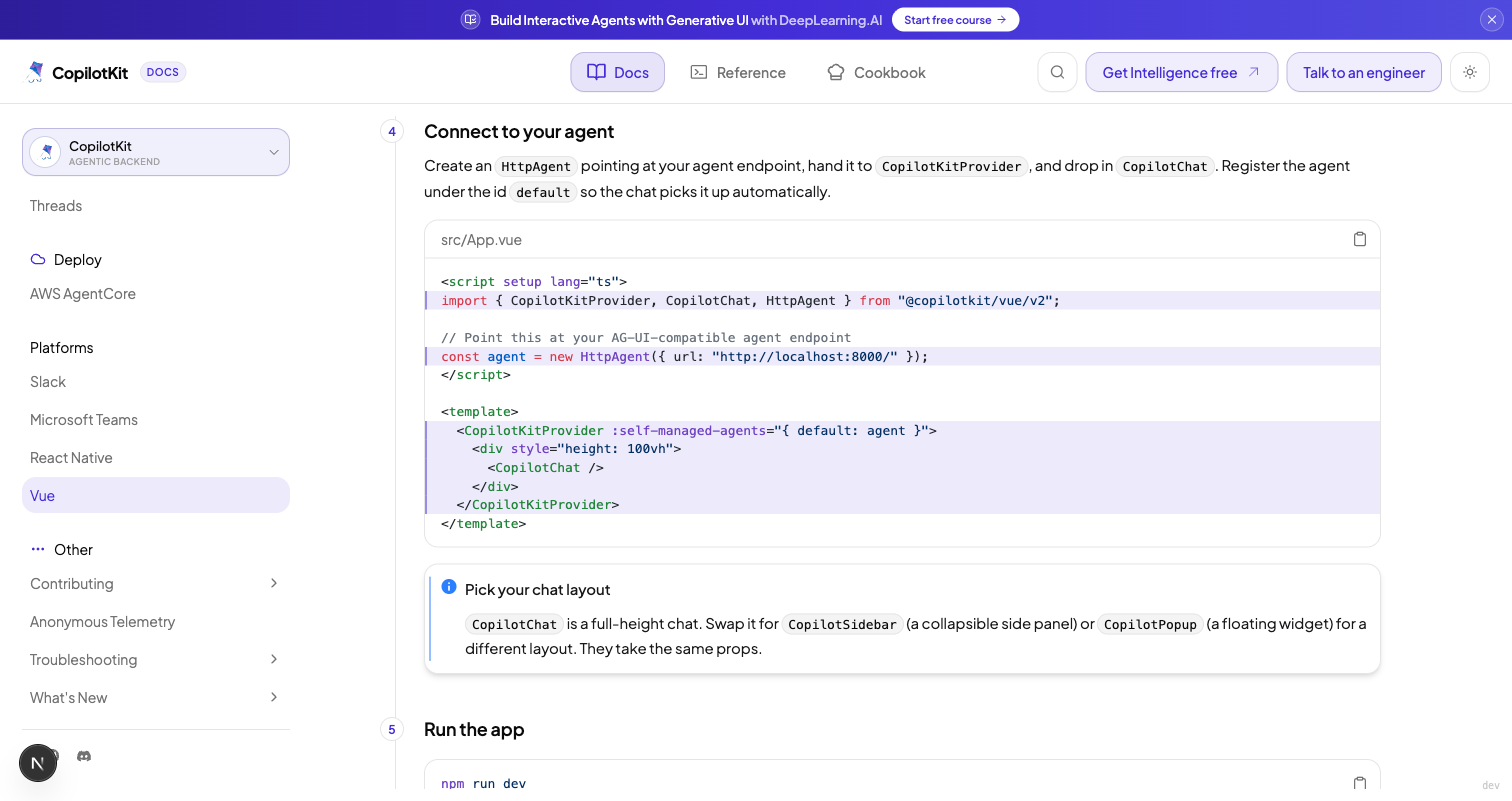
- `showcase/shell-docs/src/content/docs/vue.mdx` (new): five steps from
`npm create vue` to a working chat connected to an agent, plus a
troubleshooting accordion and next-steps links.
- `meta.json`: adds `vue` to the Platforms nav after `react-native`.
### Verification
- `pnpm build` of shell-docs passes: TypeScript clean, all static pages
generated, no errors.
- Built a throwaway Vue app from this guide verbatim. `vite build` and
`vue-tsc` resolve every import from `@copilotkit/vue/v2` (installed via
the published `@copilotkit/vue`), the chat renders, and a message
round-trips to a local AG-UI agent and streams back.
Add a minimal getting-started guide for @copilotkit/vue under Platforms.
Connects a Vue app directly to an AG-UI agent via HttpAgent so there is no
runtime to stand up, and imports from @copilotkit/vue/v2 to match the v2
docs convention. Links out to Integrations for agent-side setup.
After A2 (commit 6c596d8d6) stripped toolName from the primary emit entries, sibling turnIndex:0 fallback entries became unreachable under first-match-wins. The 7 A2-target siblings (ag2/google-adk/lgf/lgts/mastra/msdotnet/csdkts toolName strip) had equivalent dead fallbacks deleted in that commit; csdkts was inconsistently treated. Removing the 2 dead entries restores cross-fleet consistency. Probe contract unaffected — toolCallId-gated narration entries still emit the required content phrase.

(cherry picked from commit 9720636519f4cd858fcdc08ed84597be05604a2e)
crewai-crews/ms-agent-python/pydantic-ai catchall AAPL entries still carried stale $189.42/up 1.27% narration and toolCall args lacking price_usd/change_pct. Round 1 CR finding #3 was identified but never given a fix agent. Brought all 3 to canonical shape matching built-in-agent (A5) and csdkts narration (A6): price_usd=338.37, change_pct=-2.96, narration 'AAPL is trading at $338.37, down 2.96% on the day — rendered through the custom wildcard catchall.'

(cherry picked from commit df84657310451500278d0b3d0125c9c490042d2b)
validateCustomCatchall's requireContentPhrase branch was unreachable: assertCustomCatchall defaulted it to false and no caller overrode. The whole point of the PR is to catch cross-fixture leakage via content assertion — wiring it on. Turn-2 (Quote AAPL) now asserts the custom content phrase is present in the rendered bubbles, not just the testid.

(cherry picked from commit c9620c96f9addfee18f87fb1f8b2ae7fb040b3b8)
Probes registered fixtureFile: 'tool-rendering.json' but actual files are tool-rendering-{default,custom}-catchall.json. Field is signal-only (aimock loads directory-wide content-driven matching) but accurate metadata helps debugging. Test files updated to enforce the correct values.

(cherry picked from commit 3c9de26375546f2269870b563ecd1526ec5a3bc2)
ag2/claude-sdk-typescript/google-adk/langgraph-fastapi/langgraph-typescript/mastra/ms-agent-dotnet: AAPL is turn-1 so turnIndex:0 fallback unreachable; toolName gate fails on wildcard-renderer integrations that don't register get_stock_price. Aligned to LGP-gold pattern (userMessage+context discriminator, no toolName, no turnIndex:0 fallback). Preserved legitimate multi-pill matchers (SF/flights/d20/chain) on the 4 multi-pill integrations.

(cherry picked from commit c10821b5d904b31bee2ab2a39db3b1565aecba26)
built-in-agent shipped $189.42 vs the rest of the fleet's $338.37. Drift makes any content-asserting test on AAPL price brittle. Aligned.

(cherry picked from commit c0796da2a63abfeaa1d8ea06200df0754d30a2e6)
spring-ai retained hasToolResult:false on the Tokyo weather emit fixture — outlier vs LGP-gold and the other 16 catchall fixtures. Aligned: userMessage+context discriminator only.

(cherry picked from commit d268a88c4a3f405dfcc15b2aaccc190e61cd7ac7)
built-in-agent, crewai-crews, ms-agent-python, pydantic-ai: Tokyo turn-1 tool result makes hasToolResult permanently true → AAPL fixture never matched → 30s timeout. Aligned with agno/langroid/llamaindex/strands/claude-sdk-python pattern: rely on userMessage+context (and toolCallId where relevant) as the gate.

(cherry picked from commit 8e313cd1b043cf1c61efb82143171a28d7699c49)
The top-level docs/ folder is retired; the live docs are sourced from
showcase/shell-docs. Move the same three link fixes there and revert the
no-op edits to docs/:
- configurable.mdx: graph-api -> use-graph-api (#add-runtime-configuration)
- configurable.mdx: drop malformed %23 double-anchor on the schema link
- step-2-langgraph-agent.mdx: studio.langchain.com -> docs.langchain.com/.../studio
Closes#3190.
The testid generator in stats-bar.tsx used `label.toLowerCase()` directly,
producing fragile selectors with spaces and parens for compound labels.
After this PR's rename of "Wired" to "BE (Agent)", the testid became
`stat-be (agent)` — a CSS-hostile selector. A pre-existing
`stat-max depth` (from "Max Depth") had the same problem but predated
this PR.

Fix: replace with a proper slugifier:
  label.toLowerCase().replace(/[^a-z0-9]+/g, "-").replace(/(^-|-$)/g, "")

Resulting testids:
  "BE (Agent)"   -> stat-be-agent   (was stat-be (agent), broken)
  "Max Depth"    -> stat-max-depth  (was stat-max depth, pre-existing fix)
  "Stub"         -> stat-stub       (unchanged)
  "Unshipped"    -> stat-unshipped  (unchanged)
  "Unsupported"  -> stat-unsupported (unchanged)
  "Regressions"  -> stat-regressions (unchanged)
  "Failures"     -> stat-failures   (unchanged)

Call-site enumeration receipt (mandatory):
  rg 'stat-wired|stat-be|stat-max|stat-stub|stat-unshipped|stat-unsupported|stat-regressions|stat-failures' showcase/shell-dashboard/
    -> no matches (zero hardcoded references anywhere)
  rg 'data-testid=.stat-|"stat-|`stat-' showcase/shell-dashboard/
    -> only one hit: stats-bar.tsx:29 (the generator itself)
  rg 'stat-' showcase/shell-dashboard/tests/
    -> no matches (no Playwright/visual tests depend on these testids)

No test updates required.

Verification:
  npm run typecheck   -> clean
  npm test            -> 1088 pass / 1 pre-existing unrelated failure
                         (useLiveStatus.test.tsx R5 F5.2 — does not
                         reference stats-bar, exists on PR HEAD)
  npm run build       -> clean (Next.js lint inline; no lint script)
  NUL byte sweep      -> empty
 Alem Tuzlak

